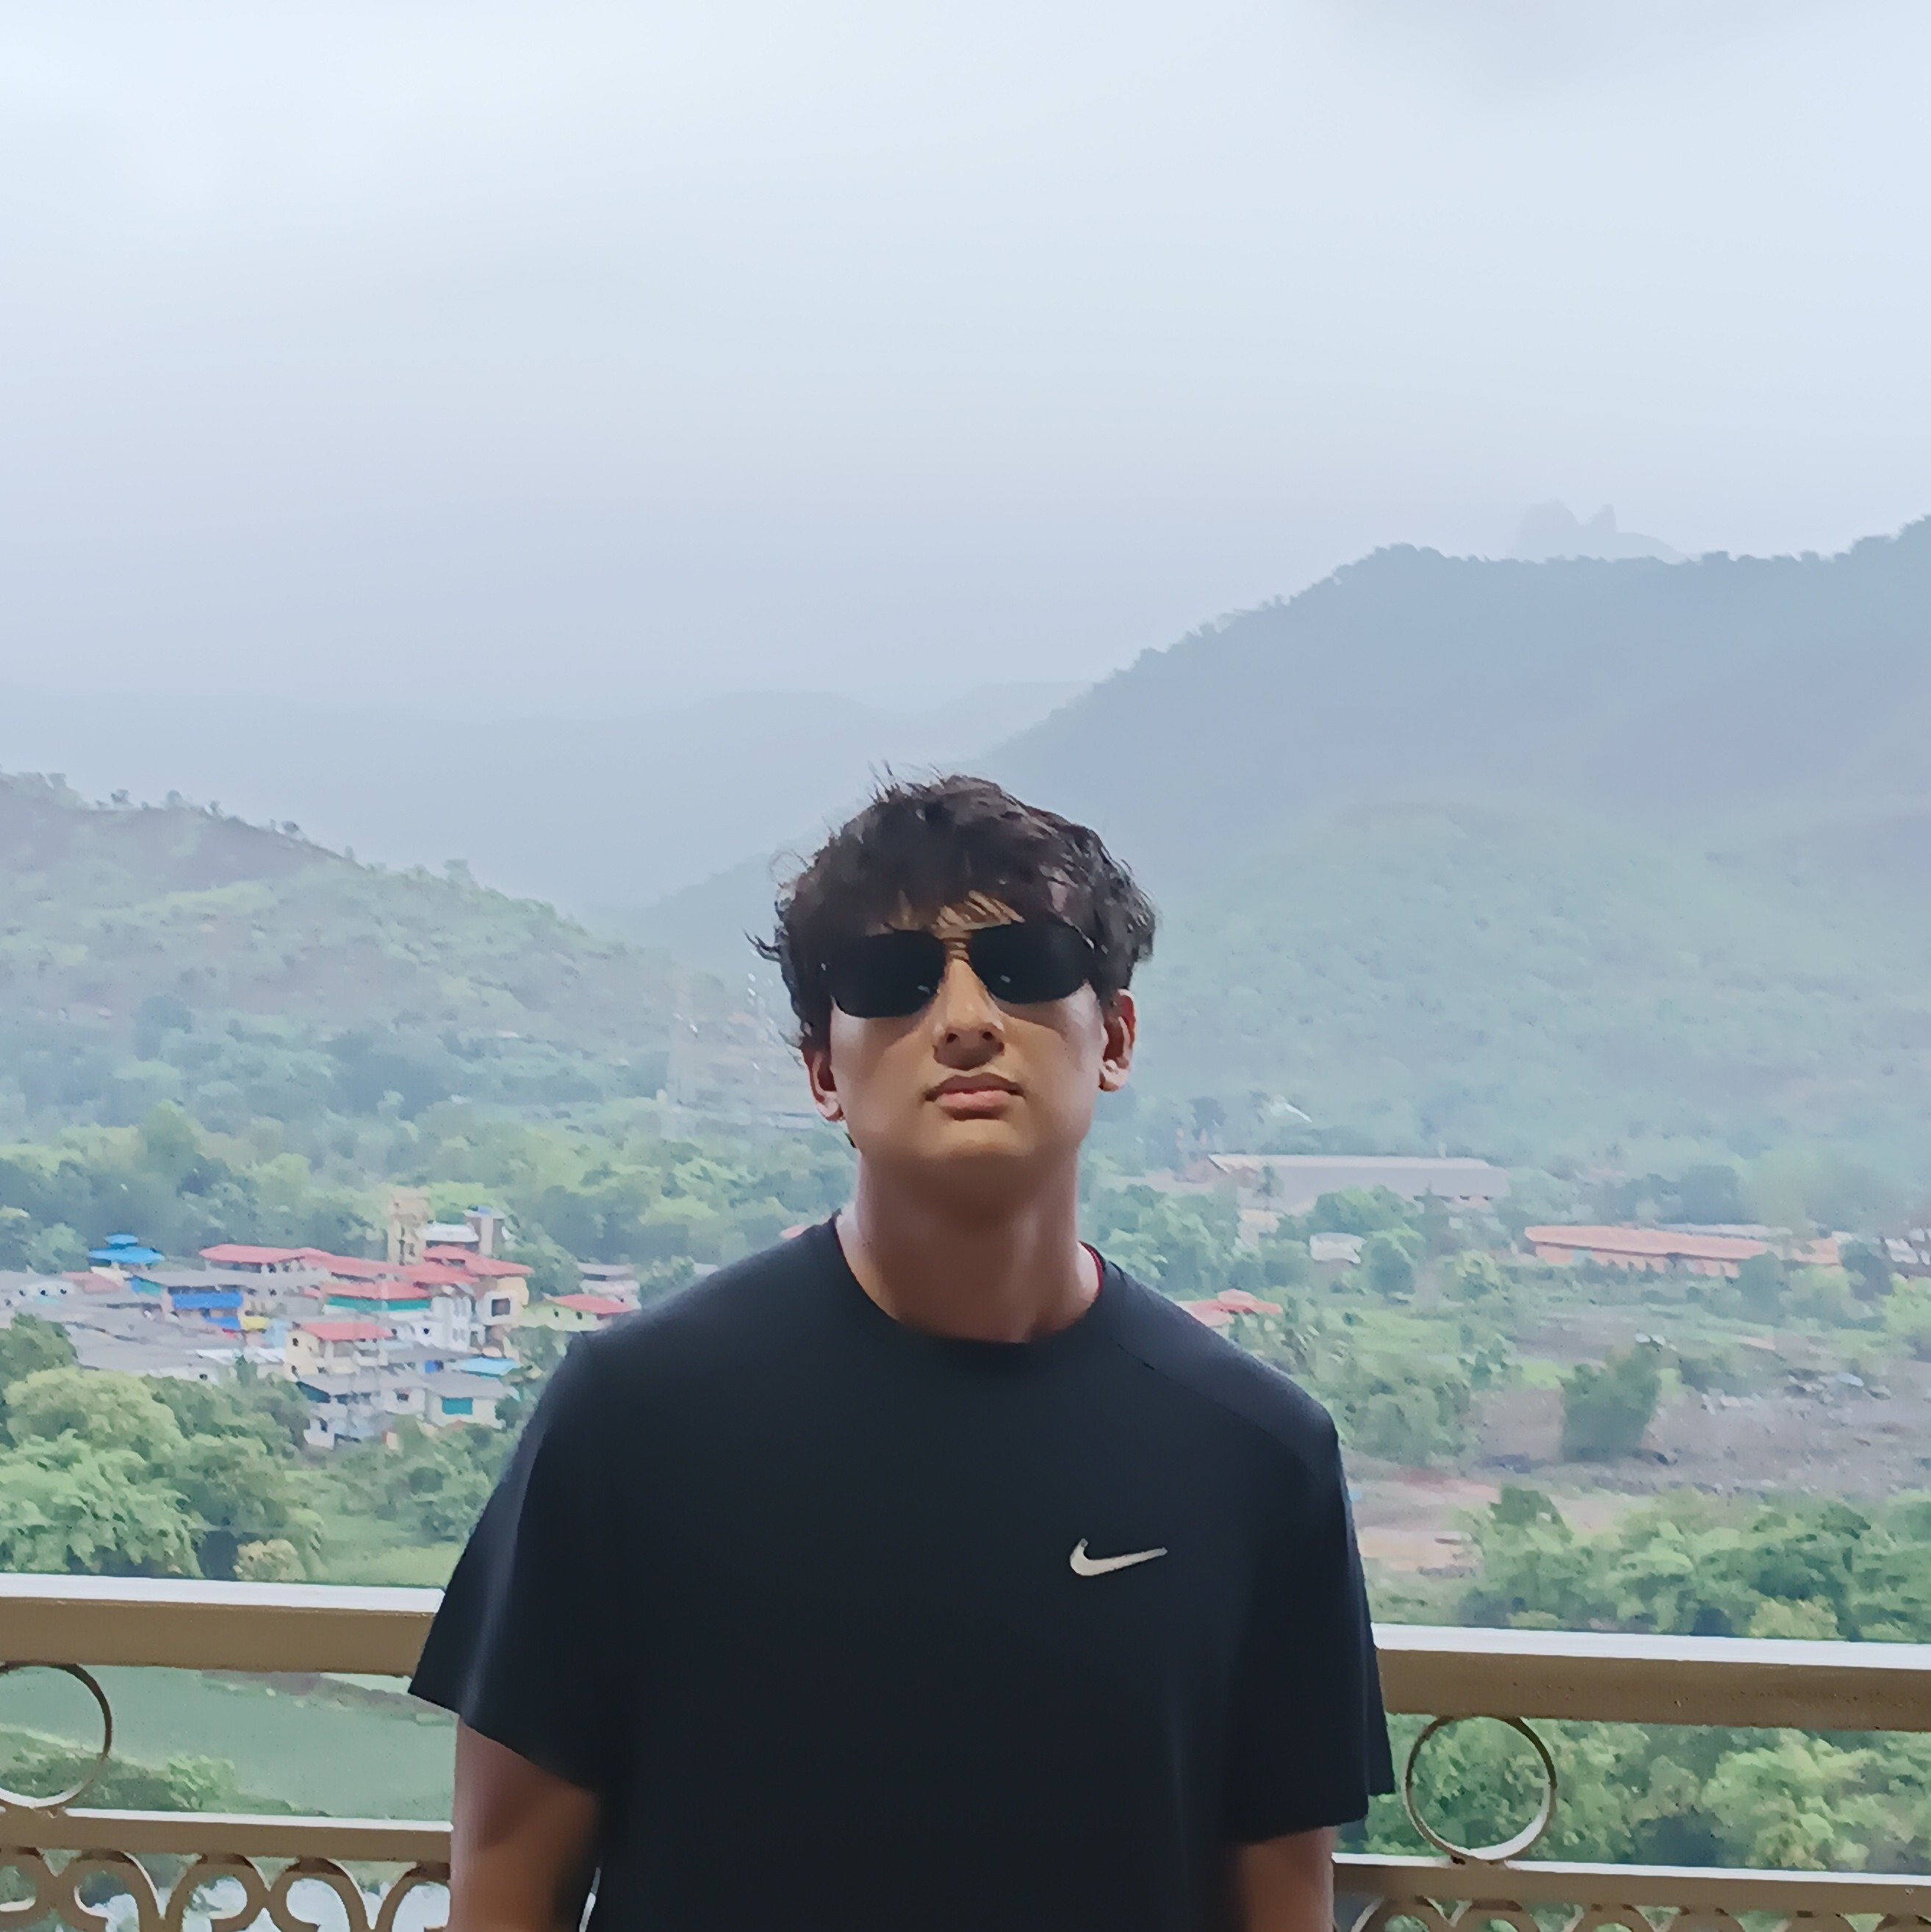
RahulRahul is the name Buddha gave to his son (it also means silver) ChandChand means "moon" in Sanskrit
राहुल चंद
Hi, I am Rahul. I completed my master's at Stanford 🌲. Most recently, I worked at Skild AI on their post-training deployment team. Before that, I was at GEAR Lab at NVIDIA Research, where I trained robot foundation models (GR00T N1.6) and worked on RL. I was also an intern at NVIDIA's post-training LLM team, working on looped transformers, and contributed to Nemo-RL (async RL).
At Stanford 🌲, I was part of Prof. Dorsa Sadigh's ILIAD lab, working on what makes good robotics data good. Before that, I was a Research Fellow at Microsoft Research on model compression. My current interests are robotics (and trying to find meaning in a post-singularity world).
At Stanford 🌲, I was a Teaching Assistant for:
- CS 153 — Infra at Scale (with Anjey Midha and Michael Abbot)
- CS 234 — Reinforcement Learning (with Prof. Emma Brunskill)
- CS 224R — Deep RL (with Prof. Chelsea Finn)
In the future , I look forward to getting replaced by AGI and working as a Wallace Design Protein Farmer
 .
It was Gorky, Lenin or maybe Mayakovsky who said about the Russian revolution that the situation forced them to choose the one chance in a thousand. Because hope became infinitely greater if you took that chance than if you didn't take it. — My Night at Maud's (1969)
Publications
Under Review
CoRL 2025 Oral · Conference on Robot Learning
NeurIPS 2026 · Evaluations and Datasets Track
ICLR 2024 · International Conference on Learning Representations
Open Source
NVIDIA's open platform for humanoid robot learning — training, fine-tuning, and deploying GR00T foundation models.
Tool to check VRAM and token/s requirements for any LLM on consumer hardware. Supports ggml, HuggingFace, bitsandbytes, QLoRA, and gradient checkpointing. Used 120k+ times by 20k+ users.
Starter tutorial for inference with LLaMA in C.
NeMo RL is NVIDIA's open-source post-training library.
NeMo Gym is a framework for building reinforcement learning environments to train LLMs.
 Stanford
 NVIDIA
 Microsoft Research
 IISc
 IIRS
 BITS Pilani